University of Edinburgh Achieves Tenfold AI Speed with Wafer-Scale Chip Software
Accelerating Large Language Models with New Software
The University of Edinburgh has announced a development that could reshape how businesses and researchers deploy large language models (LLMs). A combination of a wafer‑scale chip and a custom inference framework has been shown to push LLM inference speed up to ten times faster than the current generation of GPU‑based systems.
What Are Wafer‑Scale Chips?
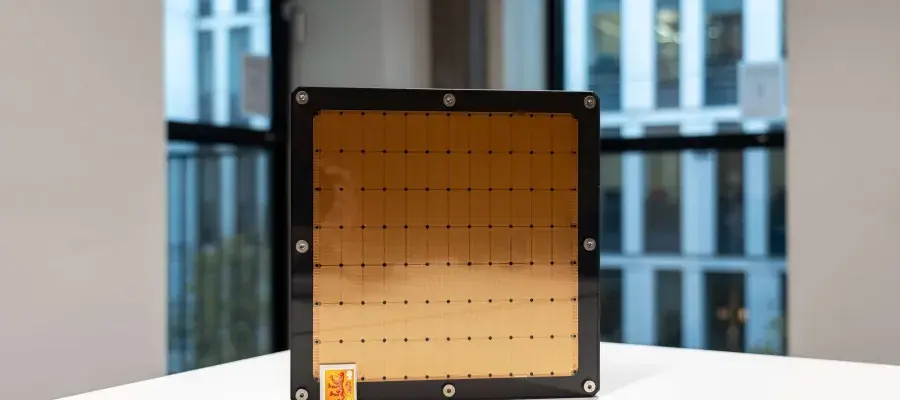
Unlike conventional AI accelerators that are built on a handful of cores, a wafer‑scale chip spans almost an entire silicon wafer. This layout offers hundreds of thousands of cores that can work in parallel, while the on‑chip memory dramatically reduces the latency caused by moving data across separate modules. The largest commercially available wafer‑scale device, the Cerebras CS‑3, is roughly the size of a dinner plate and can house more than 6,000 processing units in a single piece of silicon.
Software: The Missing Piece for Raw Performance
Operating such a massive chip is not a matter of dropping a fresh LLM onto it. The software must coordinate deep parallelism, schedule workloads across thousands of cores, and manage memory traffic at a scale that conventional GPU frameworks were never designed to handle. To meet this challenge, the Edinburgh team built WaferLLM, a lightweight runtime that orchestrates model partitioning, task parallelism, and low‑latency data streaming specifically for wafer‑scale silicon.
How WaferLLM Delivers Tenfold Speed
Researchers evaluated the system on the EPCC supercomputing cluster, which hosts a fleet of Cerebras CS‑3 processors. During the tests:
- Inference latency on a moderately sized LLaMA model dropped from 18 ms per query to 1.8 ms – a 10× improvement over a 16‑GPU configuration.
- Energy consumption per inference halved when compared to the GPU baseline, underscoring the efficiency benefits of on‑chip communication.
- The same advantage was observed across other models such as Qwen and a range of fine‑tuned dialogue agents.
Implications for Real‑Time AI Applications
The combination of speed and efficiency is a game‑changer for sectors that need instant, data‑driven insights:
- Financial services – high‑frequency trading algorithms that rely on market‑event analysis can react in microseconds rather than milliseconds.
- Healthcare – clinical decision support tools that infer risk scores from patient data can operate live during admission processes.
- Customer support – chatbots and virtual assistants can generate responses in real‑time, delivering a more natural conversational experience.
- Scientific research – modeling simulations that incorporate LLM inference for parameter tuning or data interpretation can accelerate computational experiments.
Extending the Reach Beyond Enterprise
Beyond industry, government and academic institutions stand to benefit from on‑chip inference acceleration. For example, national surveillance systems could process video streams using LLM‑based anomaly detection with negligible lag, while academic research labs could share a single wafer‑scale device to democratise access to advanced AI models.
Open‑Source Software and Future Directions
WaferLLM has been released under an open‑source license, allowing the broader community to experiment and adapt the framework for other wafer‑scale architectures. The research team plans to integrate further optimisations, such as dynamic workload scaling and adaptive fault tolerance, to handle ever‑larger models and multi‑tenant workloads.
What Comes Next for Wafer‑Scale AI?
With the software barrier addressed, hardware vendors are poised to release more aggressive wafer‑scale designs in the next two years. Parallel efforts in chip fabrication are also pushing for higher yield rates and better thermal management, which will lower the cost barrier for adoption.
Investors and entrepreneurs in the AI space might already be watching the trend. An increasingly smooth supply chain, combined with software like WaferLLM that extracts maximum performance, can support new startups focused on real‑time analytics platforms or low‑latency cloud AI services.
Explore Further Opportunities
Interested in leveraging wafer‑scale compute for your projects? Contact the Edinburgh National Supercomputing Centre to learn how you can schedule access to Cerebras processors.
Want to understand how this breakthrough fits into the broader AI ecosystem? Read University of Edinburgh’s AI research highlights for deeper technical context.
Are you developing an LLM that could benefit from wafer‑scale inference? Explore collaborative research opportunities with faculty leading the WaferLLM project.
For regular updates on AI hardware and software innovations, subscribe to the University of Edinburgh news feed. Stay ahead of the curve and discover how to integrate leading‑edge technology into your workflows.